Introducing Patriot AI MatrixPowering Local Intelligence from the Core

Local intelligence thrives on uninterrupted data flow. Patriot AI Matrix provides the responsive memory bandwidth and sustained high-speed storage necessary to eliminate system stalls, accelerate iteration, and keep creative workflows moving forward.

Customized configuration

WORKSTATION LEVEL

Pro AI Workstation

Suitable for enterprise deployment, AI developers, and professional workstations

Hardware Platform (Tested)
Threadripper PRO 9965WX 24-Core
Memory Requirements
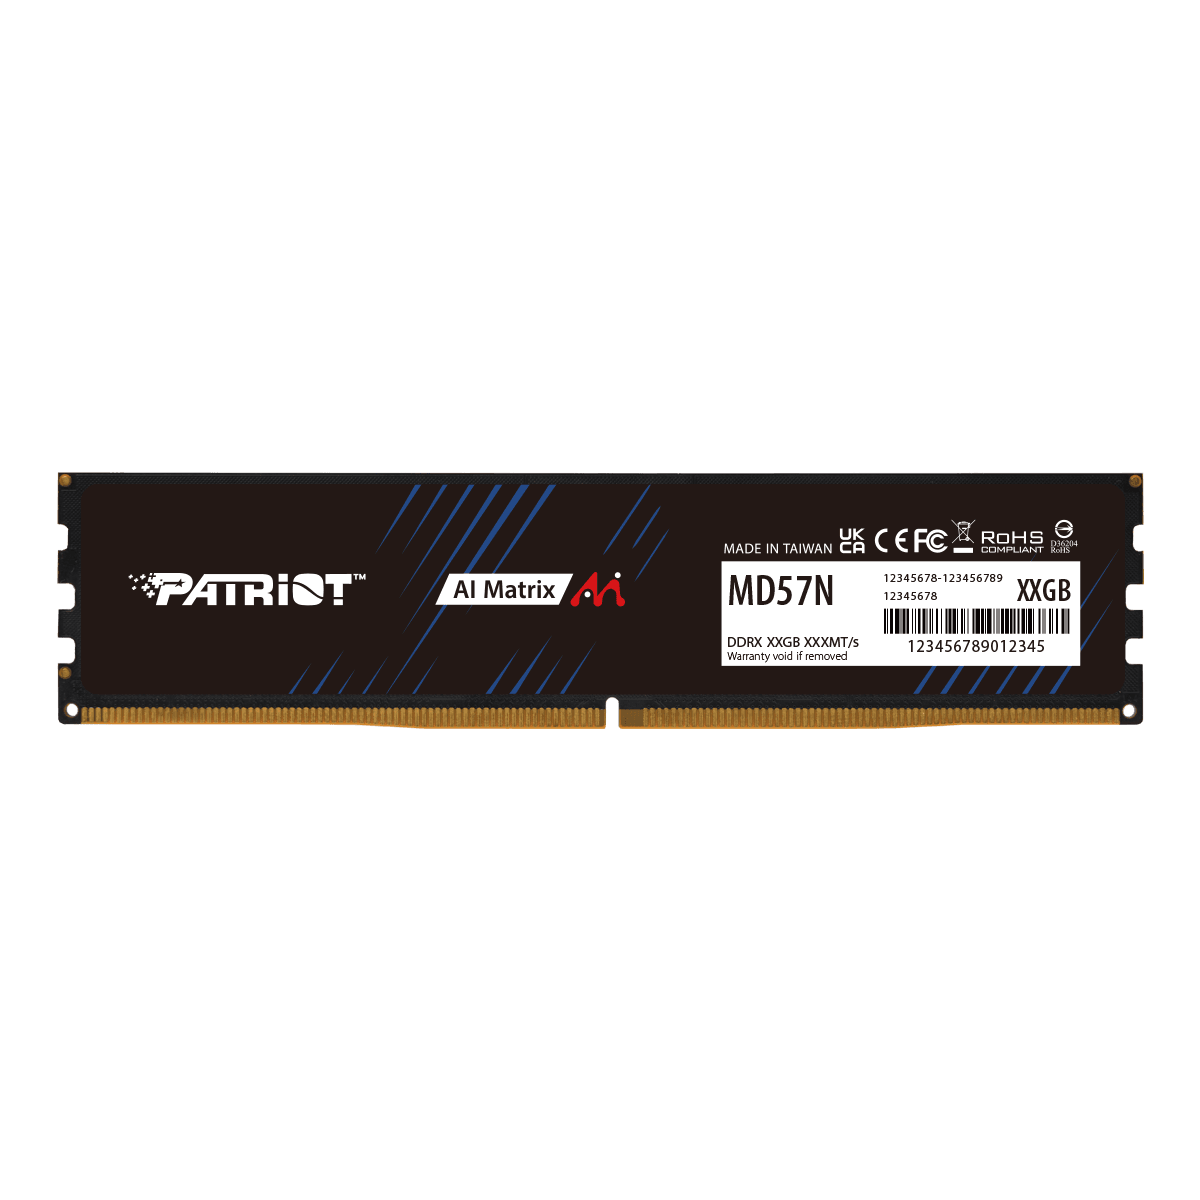
System RAM approx. 71.4GB. Full support for 70B-class large models.
Recommended: Patriot MD57N DDR5
SSD Requirements
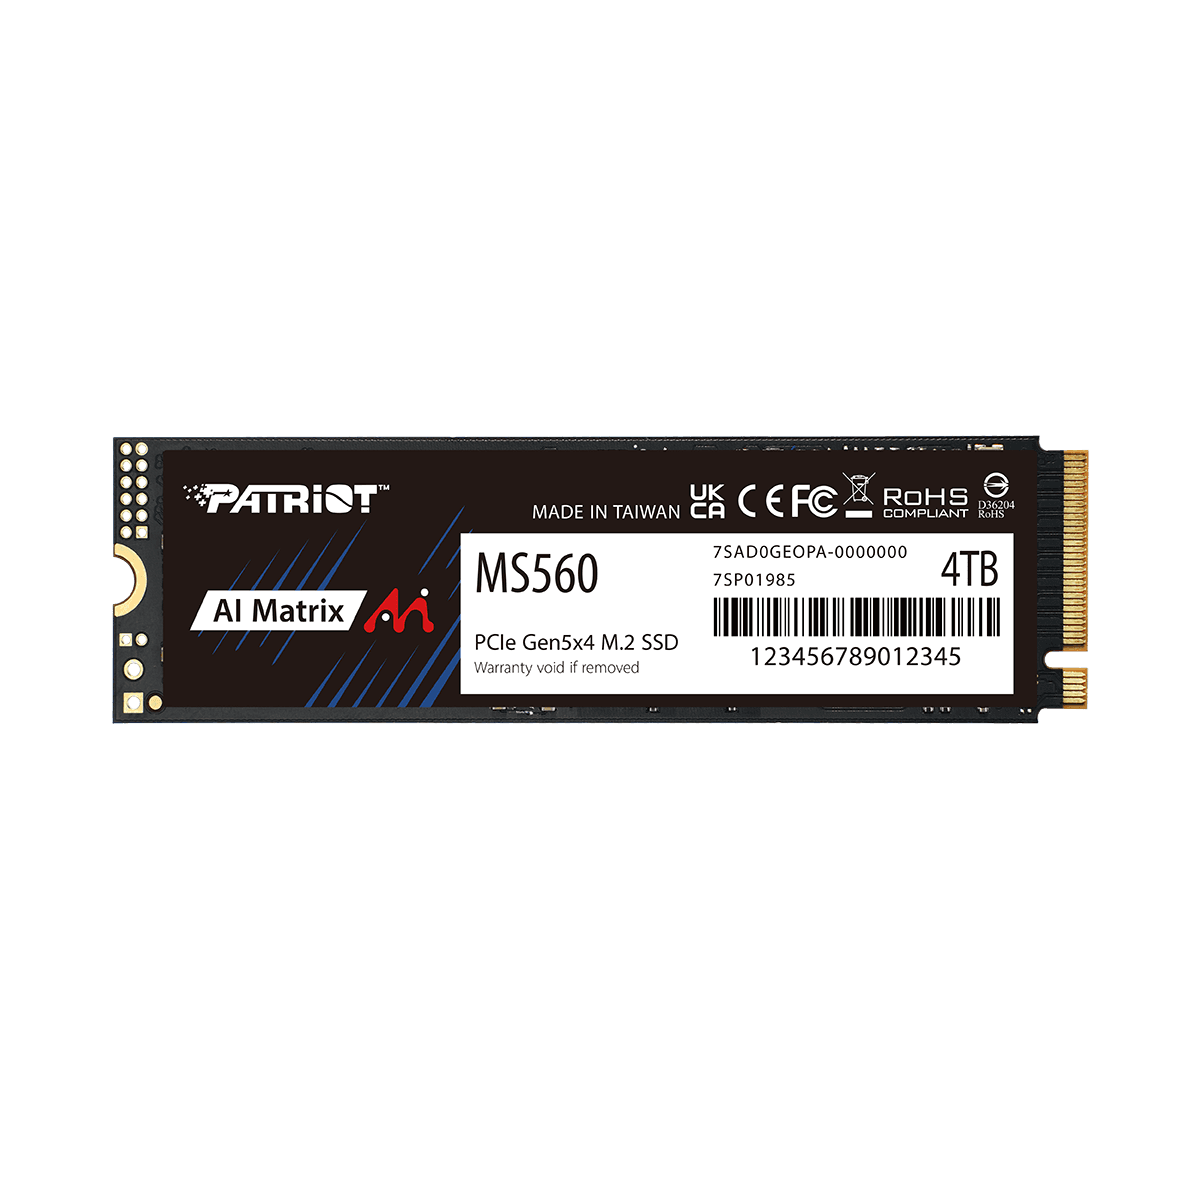
4TB, Gen5 recommended. 70B model load test: Gen5 1072 s vs. Gen3 at the same capacity tier 1177 s, over 100 seconds faster.
Recommended: Patriot MS560 SSD
Supported AI Tasks
Full 8B–70B model lineup (all passed real-world testing). 70B flagship model inference, enterprise-grade RAG, and complex task processing.
View High-End Configuration
POPULAR CHOICE

Mid AI Build

Suitable for SMEs, department-level deployment, and development/test machines

Hardware Platform (Tested)
AMD Ryzen 9 PRO 7945 12-Core
Memory Requirements
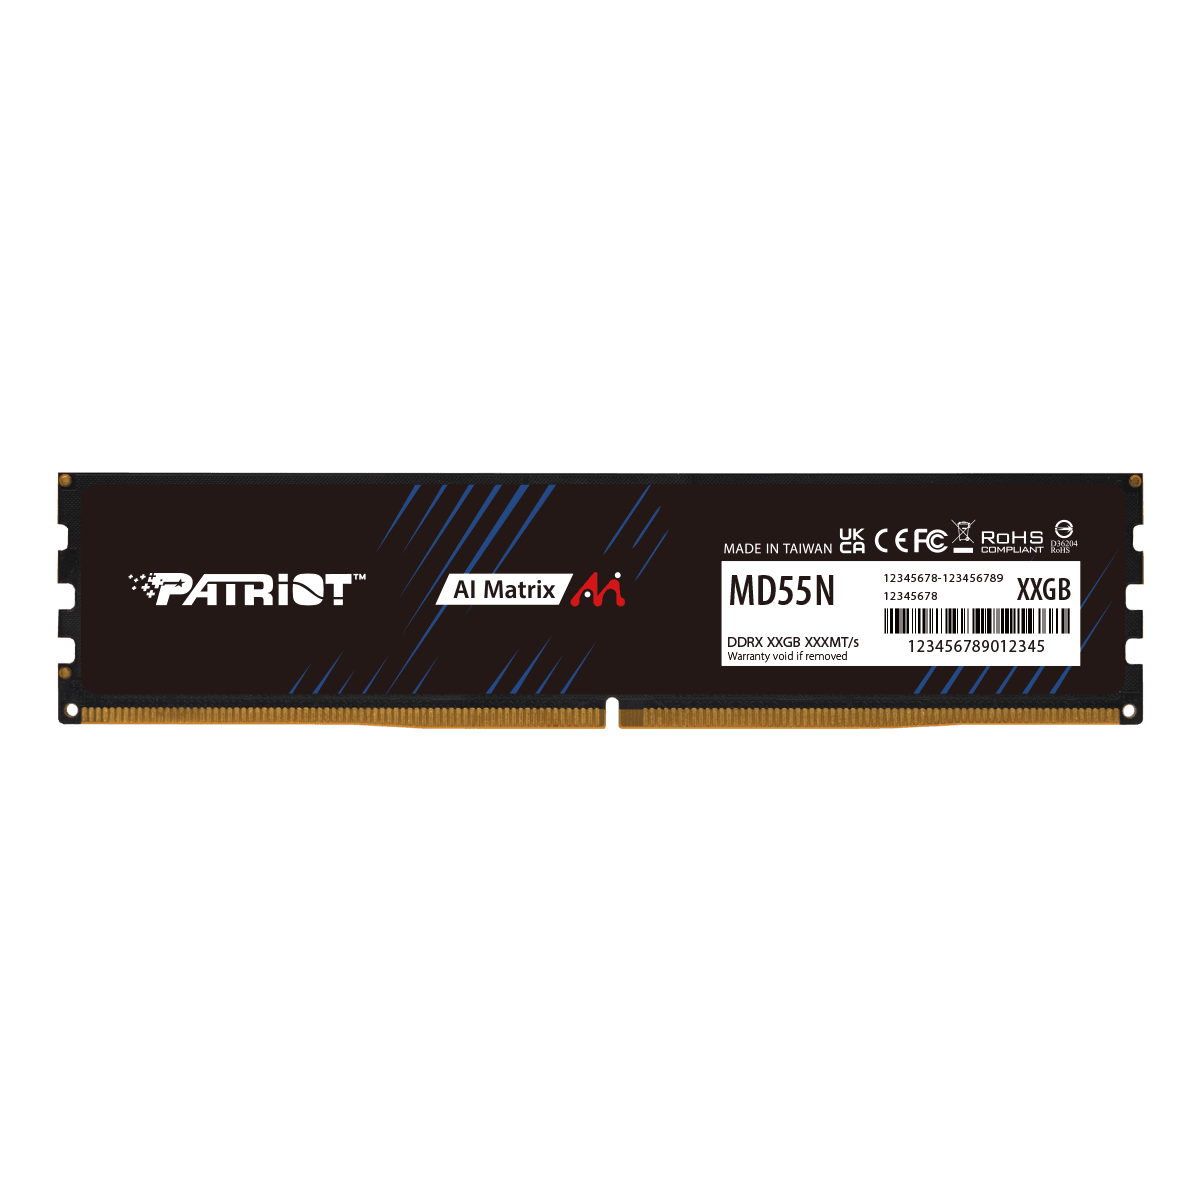
System RAM approx. 31.2GB. Supports inference up to 34B-class models.
Recommended: Patriot MD55N DDR5
SSD Requirements
2TB, Gen5 recommended. 34B model load test: Gen4 723 s vs. Gen3 772 s, so large models open faster.
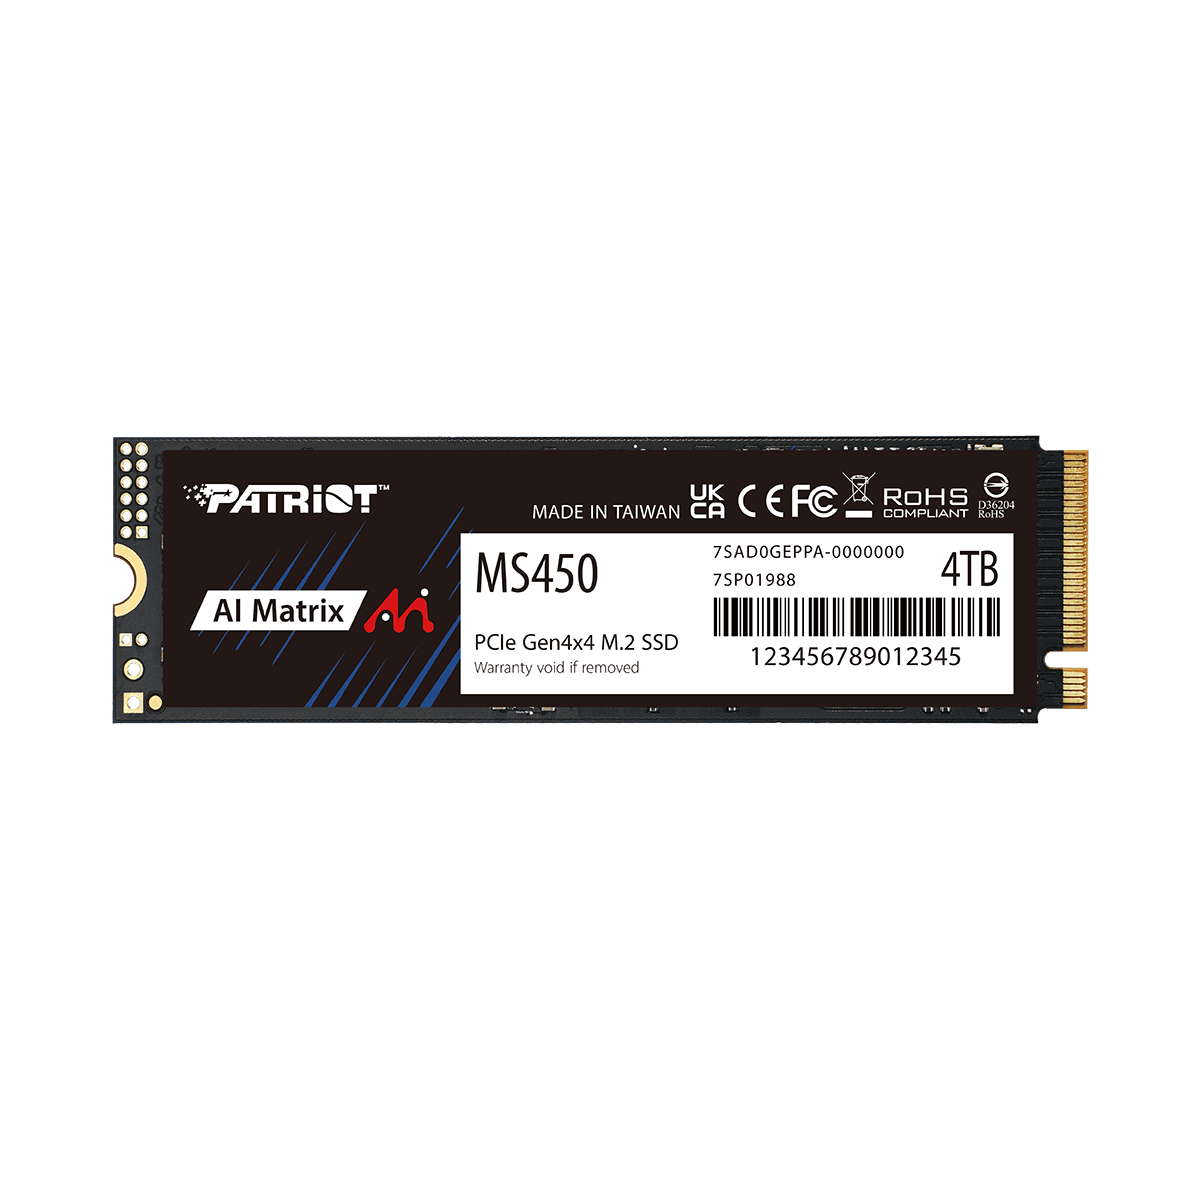
Recommended: Patriot MS450 SSD
Supported AI Tasks
8B / 9B / 27B / 34B quantized models. 8B and 9B are suitable for real-time interaction; 27B and 34B are suited for batch tasks.
View Mid-Range Configuration
ENTRY LEVEL

Entry AI Build

Suitable for individual users, lightweight chat assistants, and edge devices

Hardware Platform (Tested)
AMD Ryzen 9 PRO 7945 12-Core
Memory Requirements
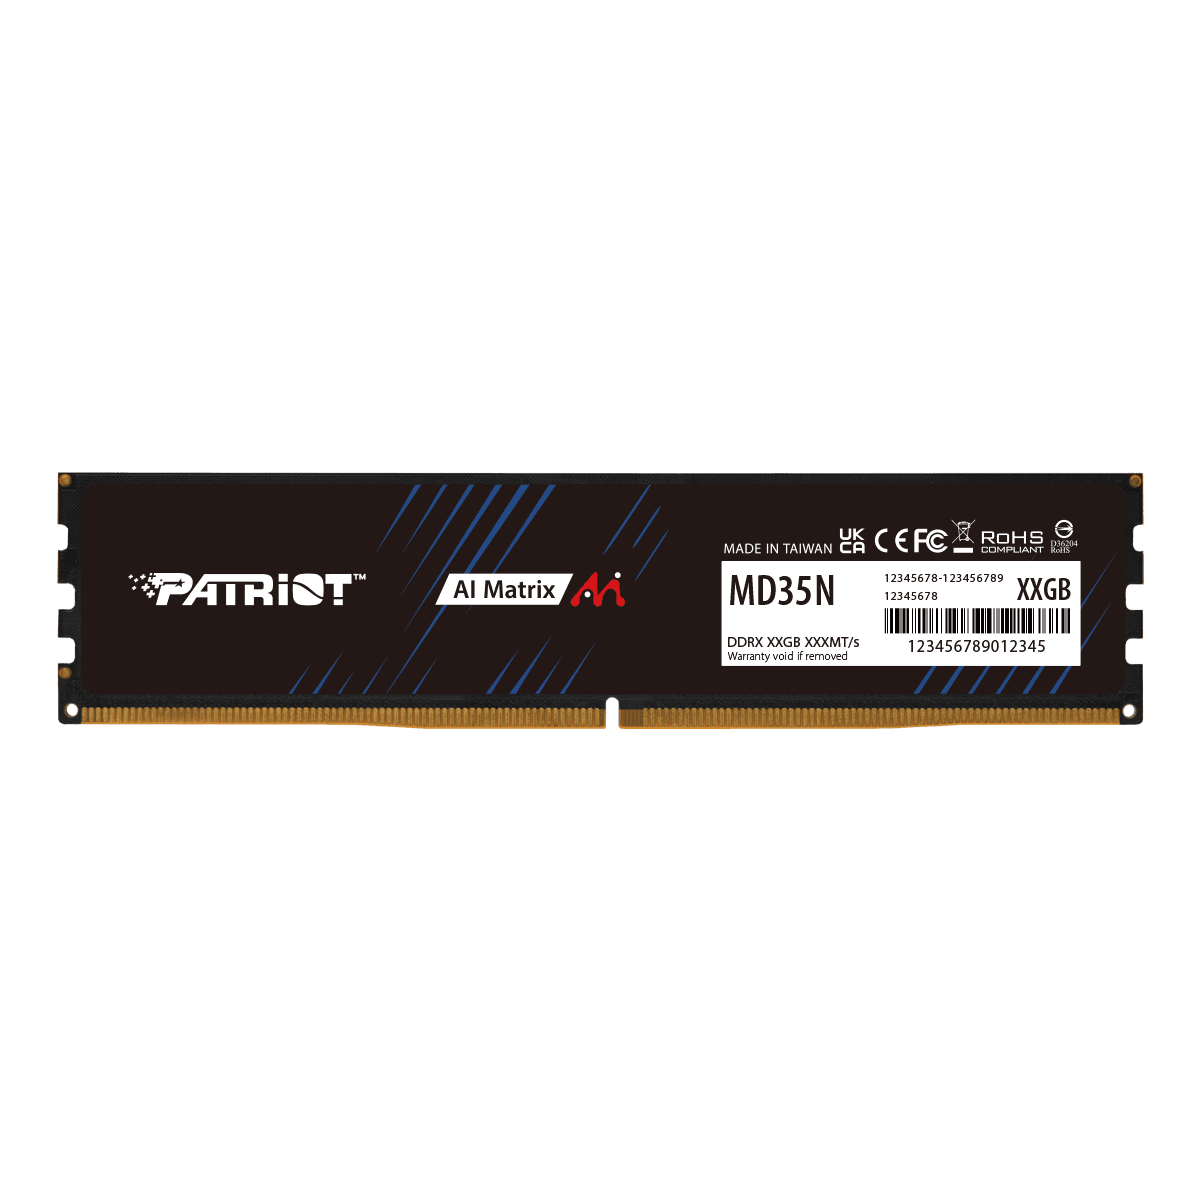
System RAM approx. 15.7GB. Sufficient to run 8B / 9B-class models.
Recommended: Patriot MD35N DDR5
SSD Requirements
512GB (Gen3 / Gen4 both work). Model files are small and the generational difference is not noticeable, so simply choose the most cost-effective capacity.
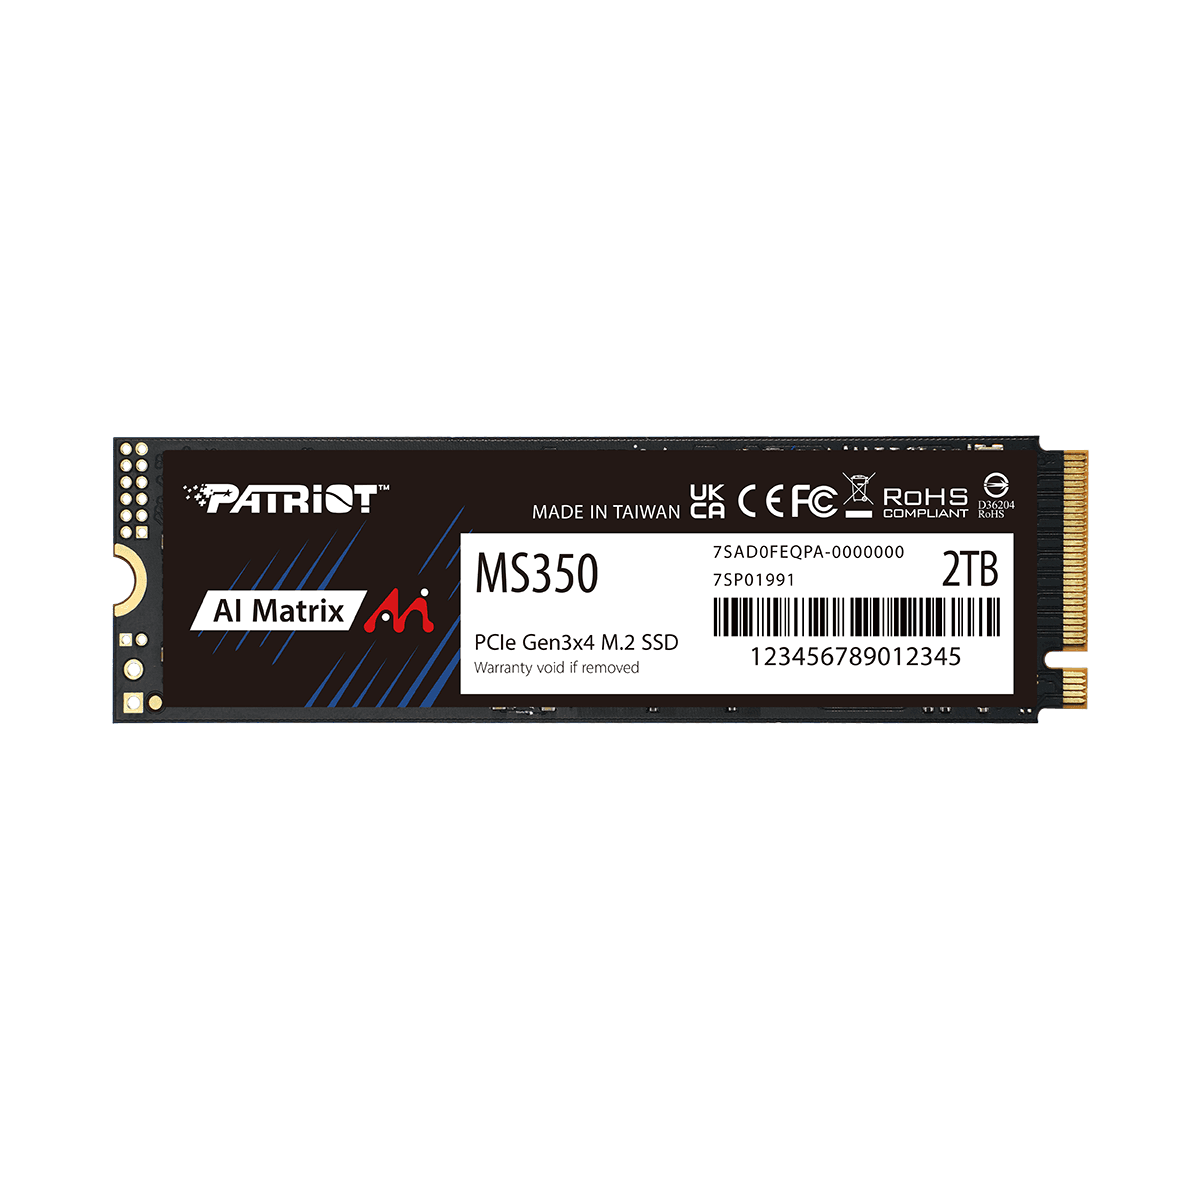
Recommended: Patriot MS350 SSD
Supported AI Tasks
8B / 9B quantized models (Llama 3.1 8B, Gemma 2 9B). Generation speed of 13–17 tok/s, suitable for real-time interaction.
View Entry Configuration

Real-world performance data

Performance by Model Size

Entry

All platforms

Model Load Time

Seconds · Lower is better
Gen5 SSD: MS560141.8 s
Gen4 SSD: MS450152.5 s
Gen3 SSD: MS350158 s

CPU Offload Generation Speed

Tokens per second · Higher is better
MD57N · 48G12.59 tok/s
MD55N · 32G9.19 tok/s
MD35N · 16G5.44 tok/s
Patriot AI Matrix product series

Why Patriot AI Matrix

Architected for Local Intelligence

Local AI execution demands a synchronized data path between storage and system memory.

Matched Memory & Storage

Patriot AI Matrix pairs high-bandwidth DDR5 with ultra-fast NVMe storage tailored to distinct model tiers—from entry-level exploration to demanding 70B parameter inference.

Built for Every AI Workload

By delivering instant checkpoint loading, zero-throttle sustained endurance, and high-frequency memory offloading, each hardware stack ensures your local models deploy faster, run cooler, and remain completely under your control.

Customized Selector

Recommended Combo

Entry · 7B–14B

DRAM
MD35N · 16GB · 4800MT/s
SSD
MS350 · 512GB
View configuration

AI Matrix Product Overview

DRAM / SSD Product Overview

ProductSpecificationModel RangePart Number
MS5604TB / 2TB / 1TB70B–72B7SP01487 / 7SP01531
MS4504TB / 2TB / 1TB27B–34B7SP01836 / 7SP01830
MS3502TB / 1TB / 512GB7B–14B7SP01885 / 7SP01835 / 7SP01834
SSD

SSD Product Sheet

Explore specifications for the AI Matrix SSD range.

Download PDF
DRAM

DRAM Product Sheet

Explore specifications for the AI Matrix DRAM range.

LLM Model Overview

Real-Time Conversation Assistants (7B–14B)

Generation speeds of 13–17 tok/s, equivalent to approximately 15–20 Chinese characters per second, support real-time interaction for AI PC personal assistants, customer service, and edge devices.

Code Generation and Mid-Size Reasoning (27B–34B)

Prompt processing at 37–42 tokens per second supports specialized enterprise models for internal code assistants, contract review, and other professional tasks.

Deep Reasoning and Complex Decisions (70B)

Large 70B models deliver high-precision analysis in offline edge environments for privacy-sensitive industrial computing and medical diagnosis.

Recommended Combo

Entry

7B–14B

DRAM

MD35N

16GB · 4800MT/s

SSD Q4

MS350

  • 4Kcontext512GB
  • 16Kcontext1TB